Something shifted this month, and it changes what a PDF is for.
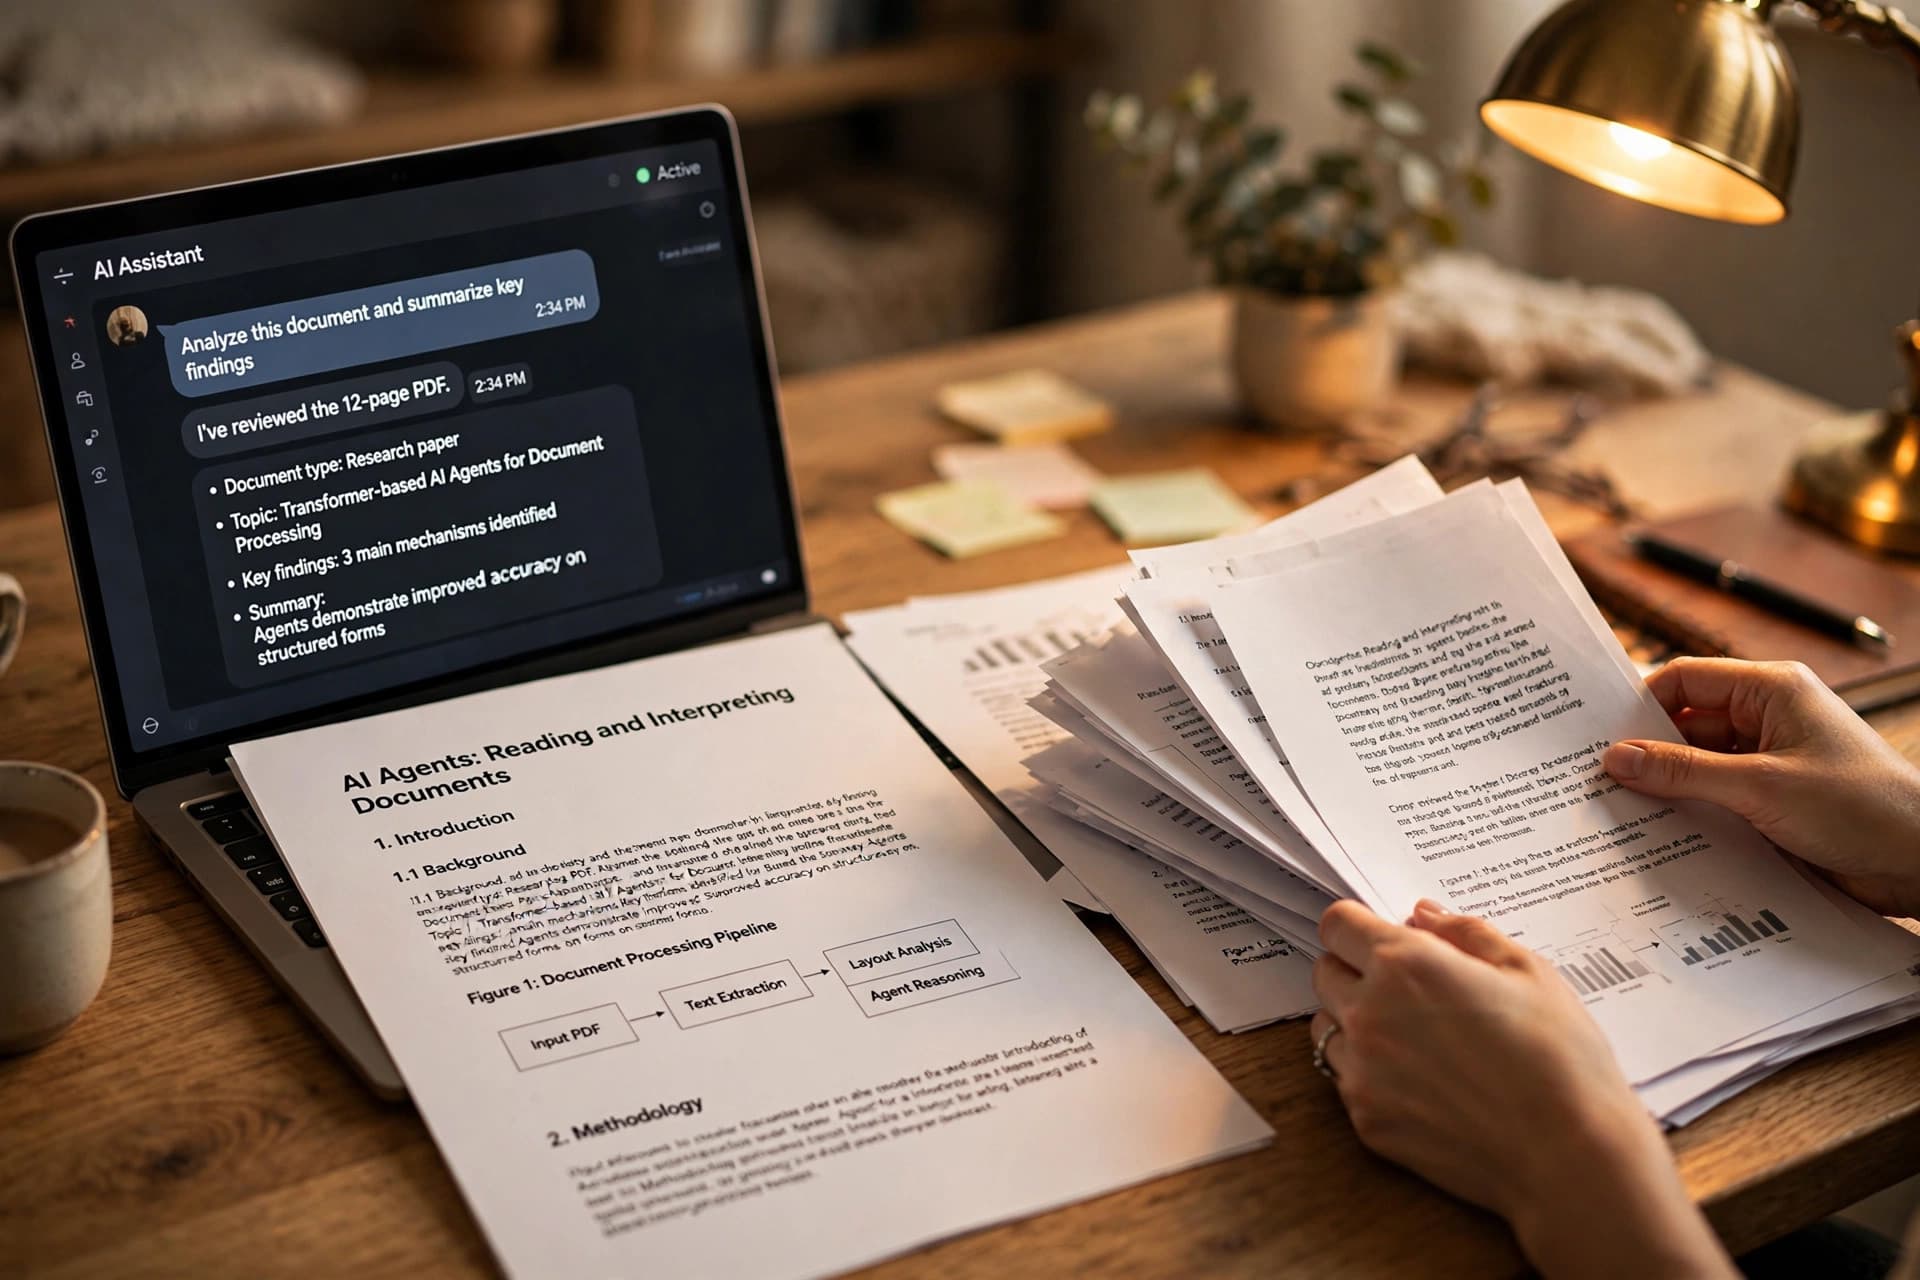
Until now, when you fed a document to an AI, you pasted text into a chat box and got words back. Now the AI reads your actual files — and then acts on them. On October 8, Google Cloud announced the Gemini agent at its Gemini at Work event: a single agent that works inside Gmail, Drive, Docs, Sheets, Slides, Chat, and Calendar, takes an objective, plans the steps, and returns finished work rather than another chat message. Two days earlier, Anthropic released Claude for Google Workspace in public beta — a sidebar inside Google Docs, Sheets, and Slides that reads the file you have open, sees your selection, and edits it directly, asking before each change by default.
That's a different relationship with your documents. You're not showing the AI a page anymore. You're handing it the keys and asking it to get the work done. Which means the file itself matters more than ever — its structure, its order, what's readable, and what's accidentally still in there.
What actually happens when an agent "reads" your document
Strip away the marketing and an AI agent does something unglamorous: it extracts content from your file, processes it, and takes actions based on what it found. It reads in the file's stored reading order. It can only interpret text that actually exists as text. It can't tell the difference between what you meant to share and what just happened to be in the file.
That last point is where most people get burned. An agent is not a careful colleague who overlooks the stray note in the margin. It treats everything in the document as data. Hidden text layers, document metadata, tracked changes, comments, embedded fonts with odd encoding, the text sitting under a decorative black box — all of it can end up in the agent's context and influence what it does. You wouldn't hand a new hire a folder with your bank passwords scribbled on the back of page three. Don't hand an agent a PDF you haven't cleaned.
There's a second, quieter problem: agents confidently misread bad files. Give it a scanned contract as image-only pages and it may hallucinate clauses instead of admitting it can't read them. Give it a report merged in the wrong order and it will summarize the wrong order without complaint. The agent returns finished work — your job is making sure the input was worth finishing.
The PDF prep workflow
Do this before any document goes to an agent, in this order.
Step 1: Check whether the PDF is text or a scan
Open the PDF and try to select a sentence. If the text highlights, the file has a real text layer — agents can read it as-is. If nothing selects, it's images of pages, and you need OCR first: run it through an OCR tool so every page gets an actual text layer. A scan that's never been OCR'd is the single most common reason agents misread documents.
Step 2: Redact before you share — for real
Agents can read everything in the file, including the things you thought you hid. If the document contains account numbers, personal IDs, salaries, or anything the agent doesn't need, remove it with genuine redaction: the content gets deleted from the file, not painted over. Drawing a black rectangle over text leaves the text intact underneath — any extractor, agent included, reads it in seconds. PDFEdit's Redact PDF tool does actual redaction in your browser. (Our full explainer on why black boxes fail lives here: redaction vs. black boxes.)
Step 3: Merge in the right order, kill the duplicates
Agents read pages in file order. If you merged the appendix before the executive summary, that's the story the agent tells. Open the merge tool, arrange files and pages in logical reading order, and drop duplicated pages while you're at it — duplicates inflate context and can make an agent double-count figures. If the original merge already happened, use organize/reorder to fix the sequence without rebuilding the file.
Step 4: Flatten and clean the structure
Interactive layers confuse machine readers. Flatten form fields, annotations, and layered comments so what you see is what's in the file — nothing interactive, nothing toggleable, no "hidden" layer the agent might read as the main text. While you're at it, check the document properties and metadata: author names, company info, edit history, and software traces sit in metadata fields most people never look at. Strip anything you wouldn't say out loud in the meeting.
Step 5: Remove passwords and permissions
A password-protected PDF will stall most agents — they can't read what they can't open. If you're deliberately sharing the file with an agent, remove the password first. (Keep it on the original you archive; hand the agent a prepared copy.) Same logic as everything here: the file the agent sees should be purpose-built for the agent.
Step 6: Keep the untouched original
Always keep a pristine copy of the document before you redact, flatten, or strip anything. Redaction is destructive by design — you can't undo it. Save the original as contract-original.pdf, do your prep work on the copy, and hand the agent only the copy. If the agent's output looks wrong, you can diff its work against the source instead of guessing.
What never to hand an agent
Even with a clean file, some documents shouldn't go to an agent at all: anything under attorney-client privilege, unreleased financials, medical records, or credentials — API keys, passwords, tokens accidentally left in an appendix. And read the data policy of the agent you're using. Anthropic, for example, states that inputs and outputs from its Workspace extension are deleted from its systems within 30 days and aren't used to train Claude — verify the equivalent claim for whatever you're using, and assume enterprise-admin policies may differ from consumer ones.
The deeper shift is worth naming plainly. Agents don't just summarize your documents now; they edit them, move them, and act across your apps. Claude's Workspace add-on edits your files in place. Google's Gemini agent can be assigned tasks that run for hours, writing results back into your docs and inbox. The quality of an agent's work is bounded by the quality of the file it read — and the safety of it is bounded by what's in that file. Preparing your PDFs isn't busywork anymore. It's the job.